LlamaQ6 – Native AI Inference Server for QNAP
Run Large Language Models Locally on Your QNAP NAS — Powered by llama.cpp
Overview
LlamaQ6 transforms your QNAP NAS into a private, self-hosted AI inference server, allowing you to run Large Language Models (LLMs) directly on your own hardware.
Built around the powerful and efficient llama.cpp inference engine, LlamaQ6 provides a dedicated web administration console, intelligent CPU/NVIDIA GPU detection, GGUF model management, and an OpenAI-compatible API designed for seamless integration with Open WebUI.
Keep your AI models and conversations within your own infrastructure, without relying on external inference services.
Key Features
Native QNAP Integration
- Runs directly on QTS and QuTS hero without Docker or Container Station.
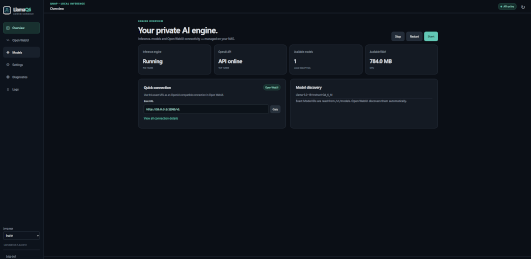
- Integrated QTS application window with a modern dark-themed interface.
- Dedicated start, stop, restart and diagnostic scripts.
- Multilingual administration interface with 20 language options.
Intelligent CPU & GPU Management
- Dedicated CPU inference engine.
- Optional NVIDIA CUDA-accelerated inference engine.
- Automatic detection of NVIDIA GPUs and QNAP NVIDIA GPU Driver packages.
- Automatic selection of the appropriate backend at startup.
- CPU fallback when GPU acceleration is unavailable or fails.
- Detailed CPU, GPU, driver, runtime and backend diagnostics.
GGUF Model Management
- Support for quantized GGUF language models.
- Automatic download of an initial lightweight Llama model.
- Web-based model discovery, download and management.
- Multiple-model support with on-demand loading.
- Download progress tracking and recovery features.
Open WebUI Integration
- OpenAI-compatible REST API powered by llama.cpp.
- Dedicated connection panel with all required settings.
- One-click copy buttons for server URLs, API keys and model information.
- API connectivity checks and model discovery.
- Compatible with Open WebUI and other applications supporting OpenAI-compatible endpoints.
Web Administration & Monitoring
- Responsive web management dashboard.
- CPU, memory and backend information.
- Active model and server status.
- Real-time logs and diagnostics.
- Configurable inference parameters.
- Secure administrator authentication and API key management.
- Initial administrator password delivery through QNAP QuLog Center.
Open WebUI Connection
Connecting LlamaQ6 to Open WebUI is straightforward.
API Base URL: http://YOUR_NAS_IP:12965/v1
Provider: OpenAI-compatible API
Authentication: LlamaQ6-generated API key
Models: Automatically discovered through the API
The administration interface provides dedicated copy buttons for the required connection details.
Web Administration
Administration Console: http://YOUR_NAS_IP:12966
The dashboard provides centralized access to inference settings, installed models, system diagnostics and connection information.
Hardware Requirements
A compatible QNAP NAS running the supported QTS or QuTS hero environment is required.
A dedicated GPU is not required. LlamaQ6 can run entirely on the CPU.
NVIDIA CUDA acceleration is optional and requires a compatible GPU, working drivers, the required runtime libraries and a CUDA-enabled build.
Memory requirements depend on the size and quantization level of the selected model. Larger models require additional system RAM or GPU VRAM.
Privacy & Security
LlamaQ6 is designed for local AI inference. Model processing runs on your NAS rather than through a mandatory cloud inference provider.
Administrator authentication and API key protection are included. Network access should be restricted to trusted clients, and remote access should be protected through appropriate network security measures.
Model downloads require Internet access, but locally installed models can be used without an external inference API.
Source Code & License
Original inference engine: llama.cpp
Official GitHub repository:
https://github.com/ggml-org/llama.cpp
Original project license: MIT License
https://github.com/ggml-org/llama.cpp/blob/master/LICENSE
LlamaQ6 is an independent QNAP integration built around llama.cpp, with additional administration, packaging and runtime management components.
The MIT license applies to the upstream llama.cpp engine. The license of the additional LlamaQ6 components should be checked separately.
Why Choose LlamaQ6?
Turn your QNAP NAS into a private AI server without maintaining an additional Docker environment.
Whether you are experimenting with local language models, integrating Open WebUI or building your own AI applications, LlamaQ6 offers a convenient way to manage native llama.cpp inference directly from your NAS.
Your NAS. Your Models. Your AI.
LlamaQ6 is an independent community application and is not an official QNAP product. GPU compatibility, performance and available features depend on your NAS hardware, firmware and build configuration.